iFANN
    Cerca su iFANN...
    Accedi
    Home
    Notizie
    Video
    Foto
    GIF
    Esplora
    Sondaggi
    Premi
    iFAMOUS
    Wiki
    Anime
    Stanze
    Notifiche
    Messaggi
    Segnalibri
    Profilo
    WikiPremiiFAMOUSClassificheSettoriRicompense CreatorRicompense UtenteTerminiPrivacyLinee guida della communityRimozione / DMCAAiutoSviluppatori

    © 2026 iFANN

    Home
    Cerca
    Messaggi
    Avvisi
    Profilo
    Foto
    Nate
    Nate@nate_5124mo
    📱Qwen💭AI💭Tech
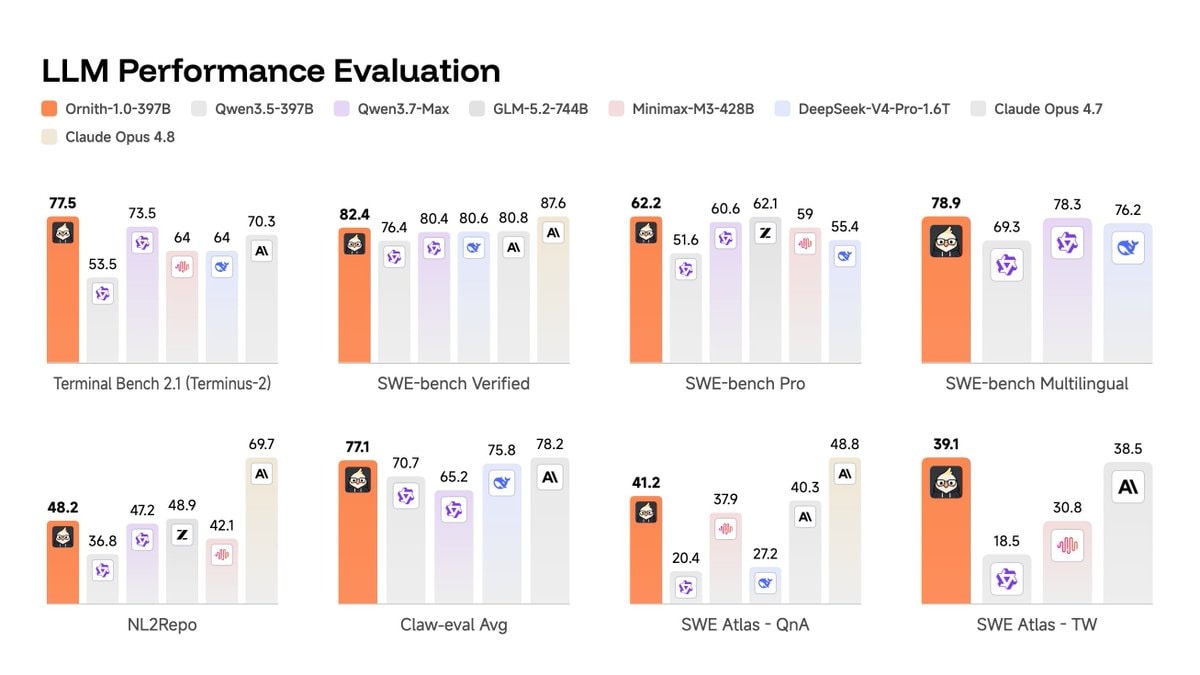
    Ornith-1.0 agentic coding LLM performance

    @nate_512Open-source models are quickly catching up to proprietary ones in agentic coding tasks. The release of the Ornith-1.0 family shows that a closed API isn't necessary for achieving state-of-the-art coding agent performance. Built on Gemma 4 and Qwen 3.5, Ornith employs a self-scaffolding reinforcement learning pipeline. Details at the link.

    Vedi post originale
    Ornith-1.0 agentic coding LLM performance

    Foto di @nate_512· Jun 27, 2026· Qwen

    Su questa foto

    The image shows a bar graph comparing the performance of various LLM models. The focus is on the graph titled "LLM Performance Evaluation". The graph displays the performance of multiple models across several benchmarks. The mood/style is formal and technical. A notable detail is the color-coded legend at the top, which differentiates between the models. There is no on-screen text beyond the title and labels, which read "LLM Performance Evaluation", "Terminal Bench 2.1 (Terminus-2)", "SWE-bench Verified", "SWE-bench Pro", "SWE-bench Multilingual", "NL2Repo", "Claw-eval Avg", "SWE Atlas - QnA", and "SWE Atlas - TW".

    Vedi tutte le foto di QwenLeggi la wiki di Qwen

    ?

    Ancora nessun commento. Sii il primo!

    Altre foto di Qwen

    Vedi tutte le foto di Qwen
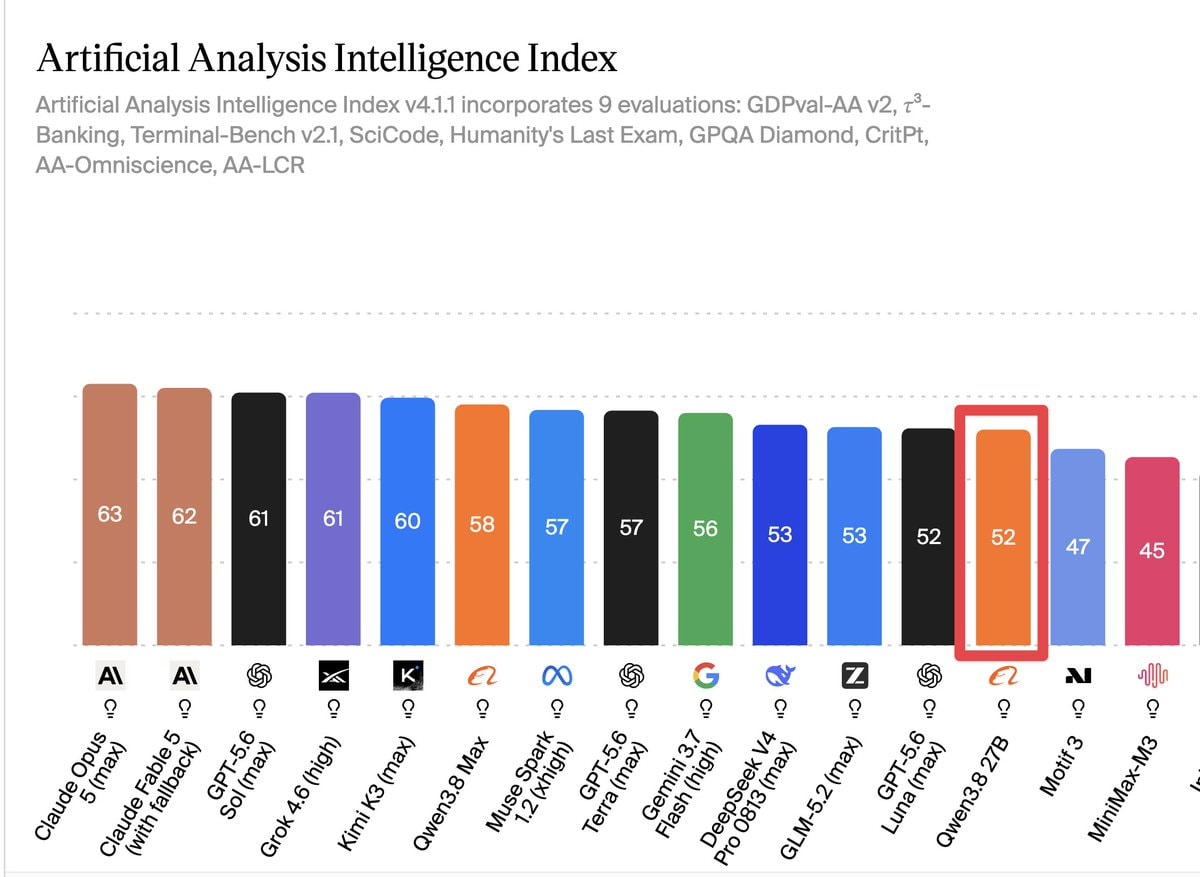
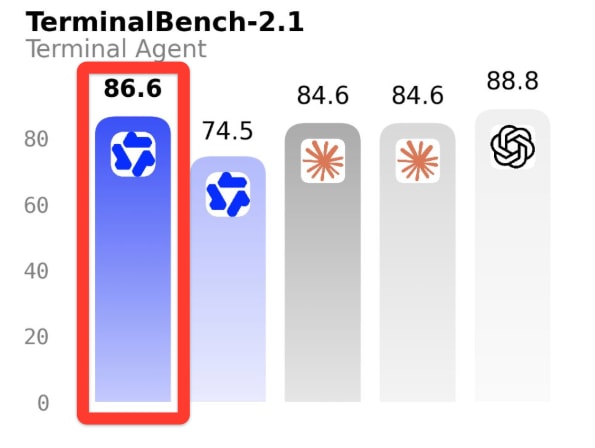
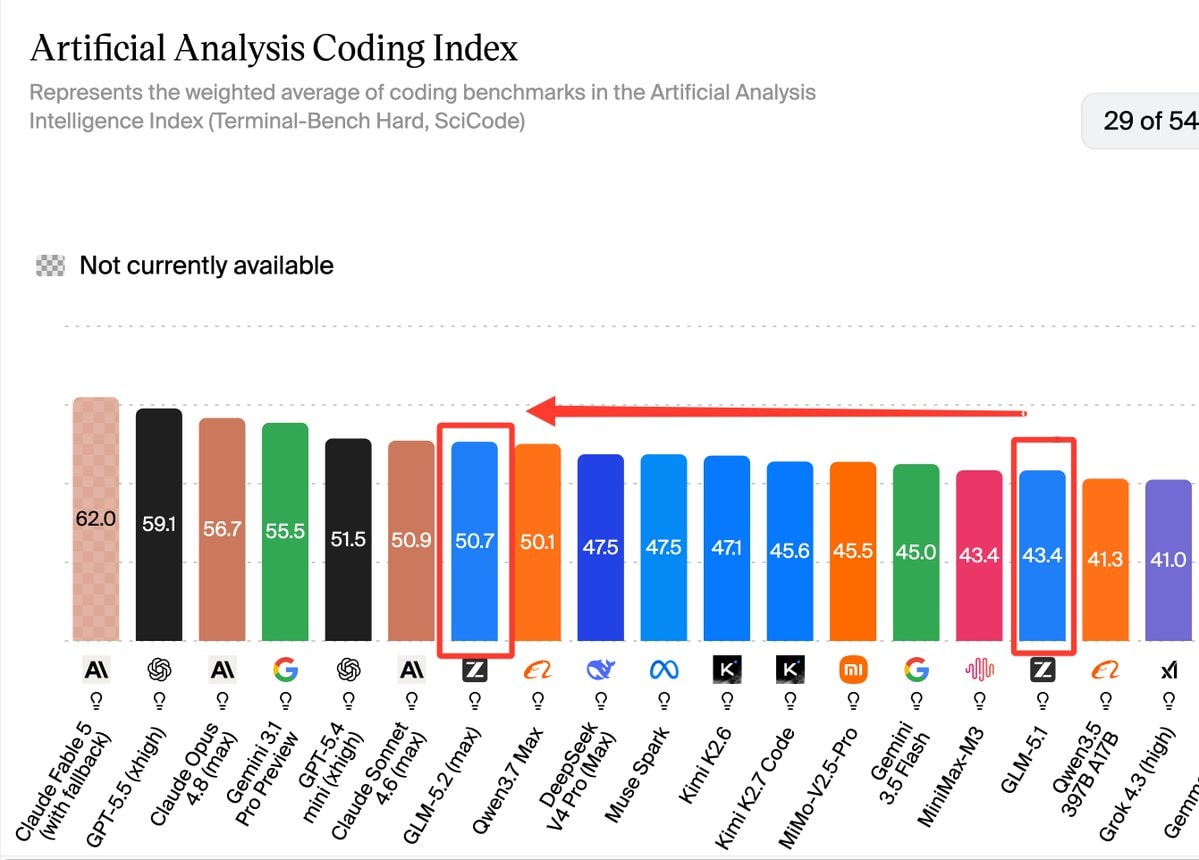
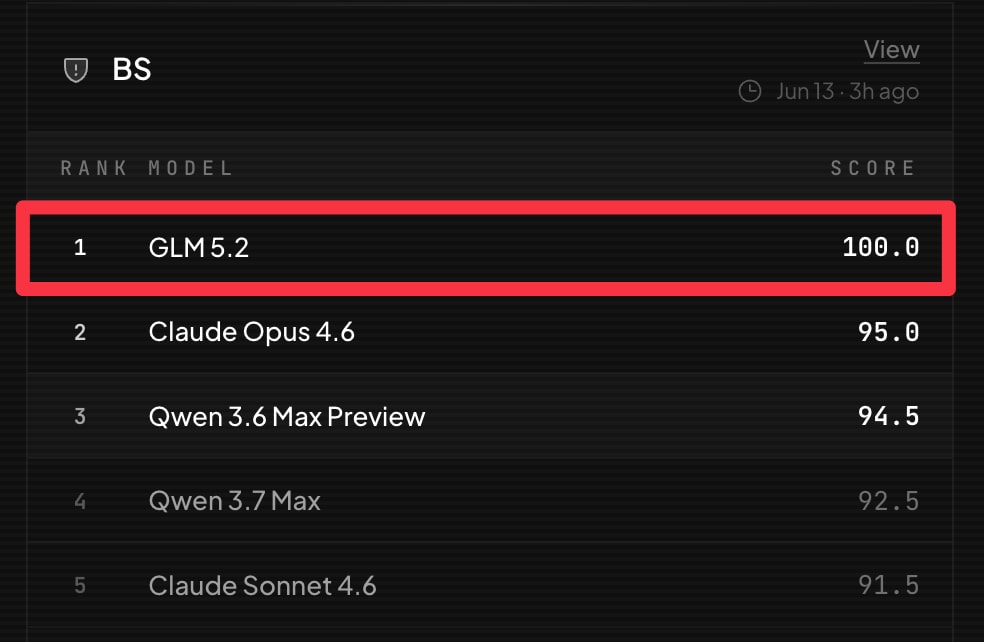
    Flint benchmark performance vs local modelsFlint benchmark performance vs local modelsGoogle WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 Max TerminalBench scoreQwen 3.8 Max TerminalBench scoreGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 perfect score BridgeBench BSGLM 5.2 perfect score BridgeBench BS
    Foto
    Nate
    Nate@nate_5124mo
    📱Qwen💭AI💭Tech
    Ornith-1.0 agentic coding LLM performance

    @nate_512Open-source models are quickly catching up to proprietary ones in agentic coding tasks. The release of the Ornith-1.0 family shows that a closed API isn't necessary for achieving state-of-the-art coding agent performance. Built on Gemma 4 and Qwen 3.5, Ornith employs a self-scaffolding reinforcement learning pipeline. Details at the link.

    Vedi post originale
    Ornith-1.0 agentic coding LLM performance

    Foto di @nate_512· Jun 27, 2026· Qwen

    Su questa foto

    The image shows a bar graph comparing the performance of various LLM models. The focus is on the graph titled "LLM Performance Evaluation". The graph displays the performance of multiple models across several benchmarks. The mood/style is formal and technical. A notable detail is the color-coded legend at the top, which differentiates between the models. There is no on-screen text beyond the title and labels, which read "LLM Performance Evaluation", "Terminal Bench 2.1 (Terminus-2)", "SWE-bench Verified", "SWE-bench Pro", "SWE-bench Multilingual", "NL2Repo", "Claw-eval Avg", "SWE Atlas - QnA", and "SWE Atlas - TW".

    Vedi tutte le foto di QwenLeggi la wiki di Qwen

    ?

    Ancora nessun commento. Sii il primo!

    Altre foto di Qwen

    Vedi tutte le foto di Qwen
    Flint benchmark performance vs local modelsFlint benchmark performance vs local modelsGoogle WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 Max TerminalBench scoreQwen 3.8 Max TerminalBench scoreGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 perfect score BridgeBench BSGLM 5.2 perfect score BridgeBench BS